This blog reports on AI in campus management. That includes the question of where AI reaches its limits – and where proven rules are the better solution. Because behind the gloss of the new technologies lurks an uncomfortable question: for many core processes at universities, classic algorithmic intelligence is not just sufficient — it is simply better.
By algorithmic intelligence we mean deterministic, rule-based procedures: a clearly defined input is processed according to explicit rules and reproducibly leads to a uniquely determined result. Learning AI systems, by contrast, derive their results from patterns in training data and work probabilistically, producing a likely result.
Which kind of intelligence fits which problem in higher education?
When the Nail Turns Out to Be a Screw
“We solve the problems with AI,” some startups promise. It sounds modern, progressive, future-proof. No wonder AI shows up more and more often in university strategies and IT roadmaps. But as so often, reality is more complex: after the peak of inflated expectations about AI and the trough of disillusionment comes the plateau of productivity. And on that plateau it becomes clear which kinds of problems can be solved with language models and which are better solved with algorithmic rule intelligence (algorithms, for short).
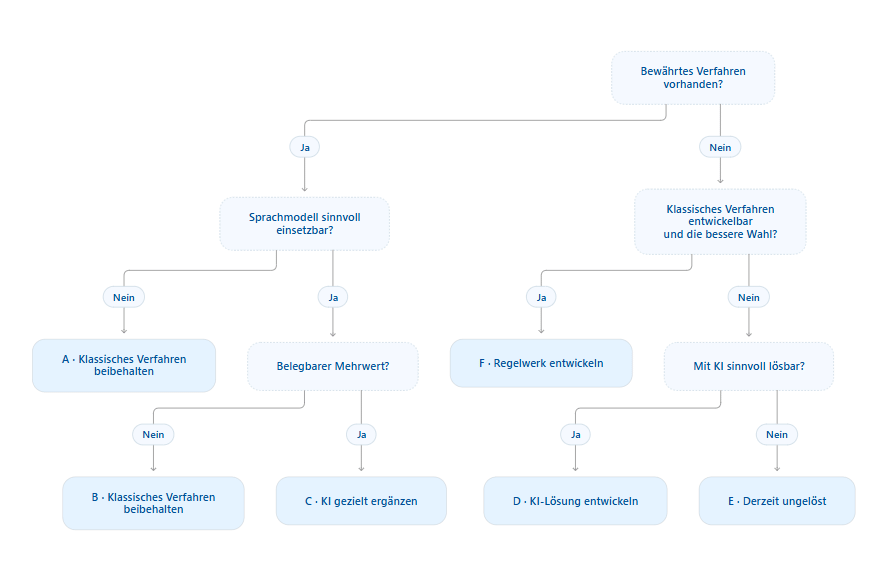
Roughly five cases can be distinguished:
A) Problems that are already solved with algorithms and that language models could NOT solve (rule task, classic)
B) Problems that are already solved with algorithms and that language models could NOT solve better (rule task, advantageous)
C) Problems that are already solved with algorithms and that language models could solve better (rule-to-AI task, added value)
D) Problems that CANNOT be solved with algorithms but that language models could solve (AI task, new)
E) Problems that CANNOT be solved with algorithms and that language models could NOT solve either
Established campus management systems have long had field-tested solutions for A and B. For them, AI becomes exciting above all for C and D. Some startups, on the other hand, advertise with “We do it with AI.” That can be misleading in two ways: not every task is solved better by AI. And sometimes “with AI” merely means that someone had the classic rule set programmed via vibe coding.
A decision logic for introducing AI-based solutions could look like this: Is there already a rule set that reliably fulfills the task? Then there needs to be a concrete need for improvement before a language model can even be considered as a replacement. If there is no solution yet, one should first check whether a clear rule set can be developed. Only when the task involves open language, unstructured information or patterns that are hard to put into rules does a learning model become particularly interesting. And even then, its benefit must be measured against the concrete result.
In other words: AI in the sense of machine learning and deep neural networks is a powerful tool for problems in which patterns have to be recognized in large amounts of data, language has to be understood or complex relationships have to be approximated. But not every problem is an AI problem. And not every “clever” solution has to be a learning AI solution. No – a proven rule set can be the better solution: simpler, more transparent and more reliable. Where no rule set exists yet, it is even worth checking whether one can be developed – before deploying a language model.
Example 1: Calculating the Average Grade
A weighted average grade according to the examination regulations is a mathematically fully defined problem. Weightings, rounding and pass thresholds are fixed. The result can be determined exactly and reproducibly with a calculation procedure. There is exactly one correct answer — and it can be calculated exactly with an algebraic procedure.
Using an AI model here that “learns” from past grading would not only be unnecessarily costly. It would simply be wrong: a model would introduce noise into the calculation where mathematical exactness is required. A grade of 2.3 under the examination regulations (on the German scale from 1.0 to 5.0) is 2.3 — not an estimate, not an approximation. Not to mention that new examination regulations with a new grade calculation would first require generating a large amount of training data.
Systems like TraiNex deliberately rely on algorithmic intelligence here: the rules of the examination regulations are coded exactly, and the calculation is deterministic and fully traceable at any time. New examination rules can be integrated quickly. For examination offices and accreditation bodies, traceability is not optional — it is mandatory.
Example 2: Detecting Student Dropout Early
Early warning systems for dropout risk are a popular field of application for AI. A model could analyze exam results, attendance and other data to produce a risk assessment.
First, however, it must be clear what task the system is supposed to fulfill. Is it about identifying, according to defined criteria, a reason to offer support? Then a rule-based warning system can be the superior solution: if a student has failed three exams and, at the same time, their attendance rate drops below 50 %, an alert is triggered — transparent, traceable, explainable. The rule is known, can be defined by the university itself, and its application can be fully documented.
If, on the other hand, the goal is to predict future dropouts as accurately as possible, that is a different task. AI prediction models can be better here, because it is about changing patterns in large amounts of data. But why the model flagged a student as a “dropout risk” cannot easily be explained — and that is delicate both in terms of data protection law and ethics. Especially with personal risk predictions, the requirements for transparency, traceability and data protection rise.
Example 3: Checking Exam Eligibility
May this student register for this exam? Have they completed the prerequisites, are they in the right semester, are all required coursework components in place? This, too, is not an AI problem. It is a rule-checking problem.
The eligibility requirements are precisely defined in the examination regulations — and an algorithm can apply these rules to thousands of registrations within seconds. Eligibility rules are configured per degree program or federal state, every registration is checked against them, and rejections are communicated with a justification. If errors occur, the rule set can be adjusted quickly and safely.
An ML model that “learns” from past eligibility decisions would not only introduce unnecessary complexity here — and with it unnecessary energy consumption and unnecessary costs. It would also carry the risk of reproducing historical injustices or making wrong decisions that cannot be explained and may not hold up legally.
The regulatory perspective is also interesting: the EU AI Act classifies certain AI systems in education as high-risk systems — among other things, when they decide on access or admission or evaluate learning outcomes. Where the examination regulations already specify clear rules, a deterministic algorithm can be not only simpler and more accurate, but also considerably less problematic from a regulatory point of view.
The Right Technology for the Right Problem
The mistake does not lie in using AI — it lies in using it indiscriminately. AI is powerful when training data is available, when patterns are to be recognized that humans cannot grasp, when language needs to be understood, or when large amounts of unstructured data need to be analyzed.
Classic algorithms are superior when the problem is mathematically fully defined, when exactness is required, when traceability is legally or ethically necessary — and when data protection and transparency are the priority.
For campus management systems, this means: grade calculation and the application of clearly defined eligibility rules belong in the hands of rule-based procedures. An early warning alert based on defined criteria can be implemented the same way. AI can complement these where it brings a demonstrable advantage — for example in understanding freely worded advisory requests or in an individual learning dialogue. And for all the problems where proven rule-based procedures do not deliver a good solution, the use of language models should be considered.
This categorical thinking can help when deciding for or against AI. As a professional, however, you should then reconnect the categories, because in the medium term the combination of rule set and language model is likely to be particularly promising. The SMARTA architecture, for example, uses the “Algorithmic Prompt Composer (APC)”, which controls a language model in a rule-based way with database access and then processes its response according to rules. Classic loops with termination conditions are also a good framework for keeping AI agents running.
Conclusion: Not the Newest Technology — the Right One
The question is not whether to use AI. The question is where it really helps — and where an existing or newly developed rule set is the better solution, or whether AI brings more risk than benefit. Universities that understand this difference make better technology decisions. And they build systems that students, teachers and accreditors can trust.
If a rule is enough, you don’t need a language model. When rules reach their limits, AI can show its strengths. Being modern does not mean building AI in everywhere. Being modern means solving the problem correctly. Sometimes with AI, sometimes without AI, sometimes in combination with a rule. And only those who know the world of rule-based algorithms can also solve a university’s problems sensibly with AI.